VOID Explained: Video Object Deletion and Privacy Impact [2026]
VOID is a Netflix-affiliated research model that removes objects from video while also updating anything physically coupled to them, going beyond simple inpainting. This post breaks down how VOID works, how it compares to production tools, and what interaction-aware removal means for creators today.
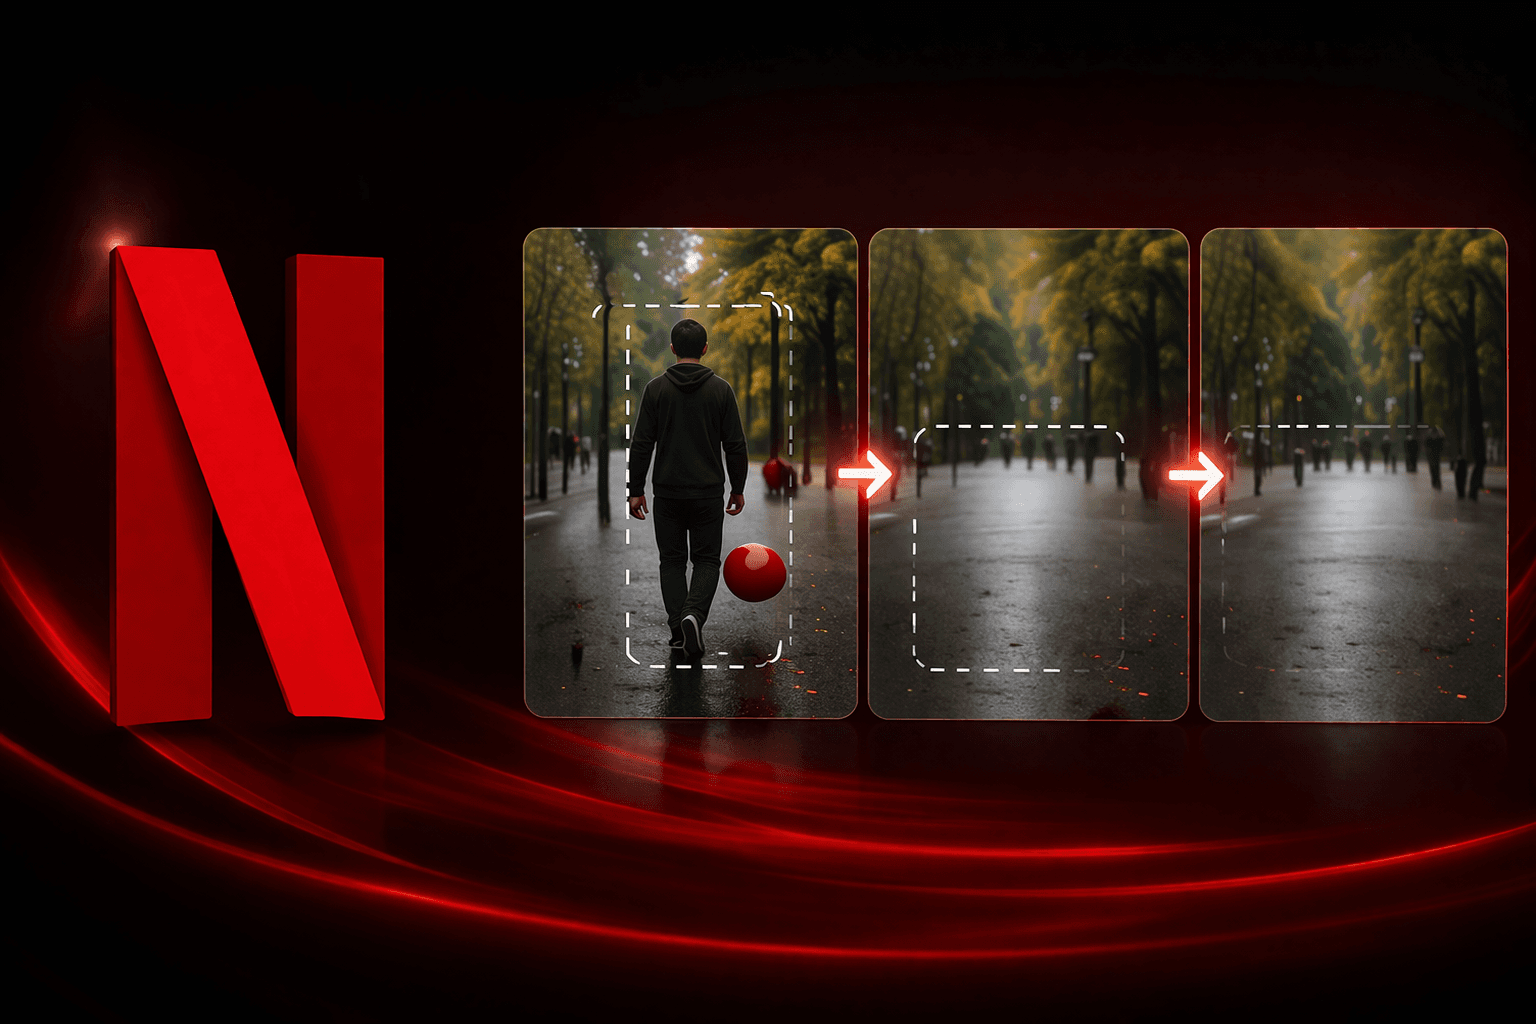
When editors talk about “removing something from a clip,” they usually mean inpainting: hide the object and fill plausible pixels. VOID (Video Object and Interaction Deletion)—from Netflix-affiliated researchers and collaborators—extends that to cases where pixels alone are not enough: if a removed object pushed, blocked, or deflected something else, the whole timeline may need to change (project site).
For BGBlur readers who polish interviews, product shots, or social cuts, VOID is a good overview of where academic video ML is headed: counterfactual video that respects simple physics, not only texture. If your goal is swapping out a distracting backdrop entirely rather than deleting a single object, our background removal and replacement guide covers that adjacent workflow.
Demo: the VOID-style clip we attached to this post
The MP4 below is the GitHub user-attachment you provided, shipped as /videos/void-demo.mp4 on this site so playback stays reliable (signed GitHub URLs expire). It is a good sanity check for smudge-free motion compared with interaction-aware removal.
How VOID works (high level)
Per the VOID site and paper (arXiv:2604.02296):
- User selection highlights an object to remove.
- A vision-language model (VLM) estimates which other regions are causally affected (things that should fall, ricochet, or reroute).
- That guidance is encoded for a video diffusion backbone described as using CogVideoX-5B with SAM 2 in the overall stack.
- A optional refinement pass uses flow-warped noise if the first synthesis morphs objects—a failure mode the authors associate with smaller video diffusion models.
Training leans on synthetic / motion-rich paired data (including Kubric and HUMOTO, as summarized on their page) so the network sees examples where “delete object A” really means “change the whole interaction.”
Runway, ProPainter, and evaluating quality
VOID positions itself against strong baselines in video object removal; on their materials you will see comparisons that include Runway-class and ProPainter-related references from the literature. Use those as paper-level guidance: they reflect specific datasets and metrics, not every real-world brief.
Across tools, creators still judge the same things: temporal consistency, lack of smears, and whether background motion looks intentional. See our deeper breakdown of temporal consistency in video anonymization for why frame-to-frame stability matters as much as the removal itself.
BGB (BgRemover) integration and what already works
BgRemover (BGB) at BgRemover.video already delivers the kind of clean, artifact-aware video object and background removal teams ship today—the baseline VOID builds on for harder physics cases.
Our roadmap: treat VOID as a blueprint for interaction-aware masking and training signals we can merge into BGB once they are robust enough for production SLAs. BGBlur stays focused on cinematic background blur and privacy-style effects, while BGB remains the home for removal—so integration work channels through the same product family you already use.
Frequently Asked Questions
What does “interaction deletion” mean?
Removing an object and updating how other objects move when they were physically coupled to it—per VOID’s framing on void-model.github.io. A simple crop-and-fill approach erases the object's pixels but leaves anything it was pushing, blocking, or deflecting behaving as if the object were still there.
Is VOID available as a consumer app?
The public artifacts today are research-grade; production tools like BgRemover continue to offer the practical path for removals right now, with reliable output on real-world footage rather than benchmark clips.
How is VOID different from standard video inpainting tools like ProPainter?
Standard inpainting hides an object and fills plausible pixels behind it, which works well when nothing else in the frame depended on that object. VOID adds a vision-language model step that flags causally affected regions—things that should fall, ricochet, or reroute once the object is gone—then encodes that guidance into a video diffusion backbone.
Can I remove objects from video today without waiting for VOID-style research to ship?
Yes. Our guide to object and region blur for video privacy covers the production-ready path: AI scene fill that erases unwanted objects from video with reliable results, processed entirely in the browser. It doesn't yet model full physical interactions the way VOID's research does, but it handles the large majority of real editing requests.
What datasets does VOID train on?
According to the project page, VOID leans on synthetic and motion-rich paired data, including Kubric and HUMOTO, so the model sees training examples where deleting one object genuinely changes how connected objects behave, rather than just examples of static background fill.
Where is the official write-up?
- Paper: arXiv:2604.02296
- Site: https://void-model.github.io
References
- Saman Motamed, William Harvey, Benjamin Klein, Luc Van Gool, Zhuoning Yuan, Ta-Ying Cheng, VOID: Video Object and Interaction Deletion, 2026. https://arxiv.org/abs/2604.02296